Two decision models: Solar Decide + Perplexity Decider
- Accepted
- 53
- Accepted errors
- 0
- To a person
- 7
$0.0375 for both runs over all 60 reviews.
 Candidate Experience
Jev is TypeSafe's decision model. You give it text and a typed question, and it returns one of your options with a probability, in one pass. We gave Jev, seven other decision models and the big general models the same 60 fictional candidate reviews, with four questions about each one. The general models, from Gemma 4 26B up to Opus 5.5, cost 3.6 to 37.7 times as much per pass. The best of the other decision models, Solar Decide, matched 55 on its first pass. The cheapest strong result came from a general model: DeepSeek V4.1 Flash with thinking off matched 54 for $0.0027, under half the price of a Jev pass, and 48 when we ran it again. Most of Jev's 6 misses sat on reviews a person would pause on. Two were plain errors, and one of those was a harassment report it marked as needing no follow-up.
If the decision matters, create a rule that hands the hard reviews to a person.
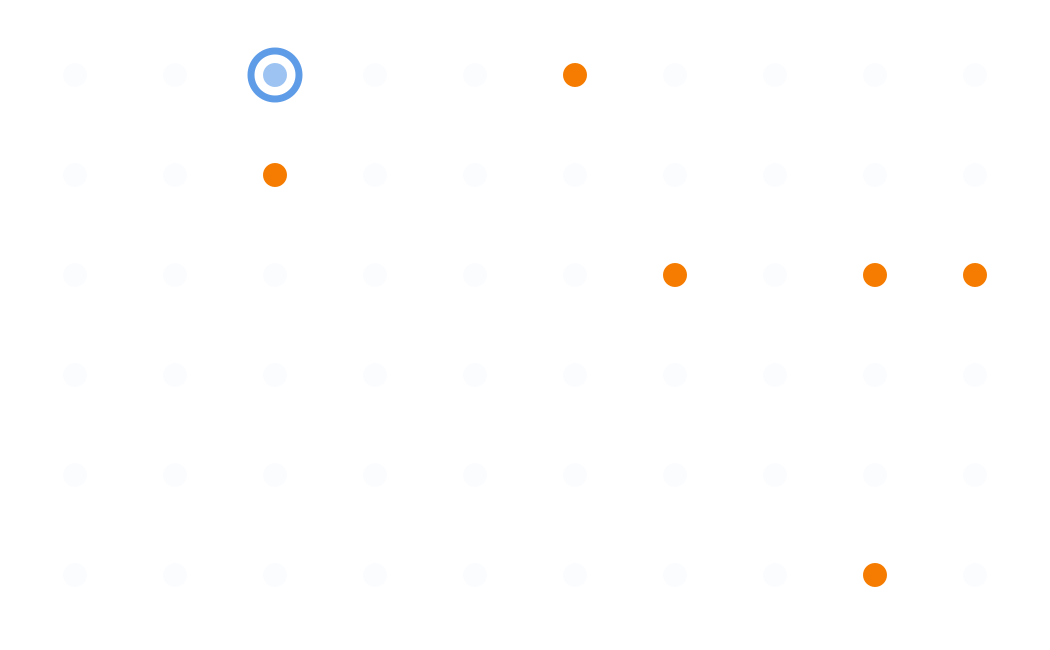
Each dot is one of the 60 reviews. Orange marks the 6 where Jev's first answers differed from the reference.
The 60 reviews are short, fictional comments from job candidates. A model answers four questions about each one, and a review counts as matched only when all four answers agree with the reference. Every model ran three prompt versions: P0 is the plain task, P1 tells the model it's a classifier, and P2 adds step-by-step decision rules. Each version ran three fresh passes.
Each cell counts the reviews where all four answers matched, out of 60. Cost is what one pass over all 60 reviews cost.
A decision model does one job. You send it the text and a question with a fixed list of answers, and it returns one answer with a probability in a single pass, with no reasoning and no free text. That makes it fast and cheap, and it also means it never stops to say the question does not fit. A general model reads the same instructions as a prompt and can reason before it answers, which costs more.
Over three fresh passes, Jev matched 54, 53 and 52 of 60. Opus 5.5 at high effort matched 59, 58 and 58. Sonnet 5.5 at xhigh matched 58 in all nine cells. The best decision model on its first pass was Solar Decide, at 55.
A Jev pass over all 60 reviews cost six tenths of a cent. An Opus pass costs 22 cents at API prices.
Jev flagged all 25 reviews the reference marks as a serious concern. It still answered no to "does someone need to follow up?" on this one, where the reference says yes:
Nice staff. After the trial shift the manager kept asking me out even after I said no twice. I've asked the recruiter to stop him contacting me.
DEV-059 Jev's four answers ↗
Jev OpenRouter native Choice
| Pass 1 | Pass 2 | Pass 3 | |
|---|---|---|---|
| P0 | 54 | 53 | 52 |
| P1 | 54 | 53 | 54 |
| P2 | 54 | stopped | 54 |
Opus 5.5 high effort
| Pass 1 | Pass 2 | Pass 3 | |
|---|---|---|---|
| P0 | 59 | 58 | 58 |
| P1 | 59 | 59 | 58 |
| P2 | 59 | 58 | 58 |
Sonnet 5.5 xhigh effort
| Pass 1 | Pass 2 | Pass 3 | |
|---|---|---|---|
| P0 | 58 | 58 | 58 |
| P1 | 58 | 58 | 58 |
| P2 | 58 | 58 | 58 |
"Great soup, tiny portions, wouldn't eat there again."
None of the seven decision models matched the reference on this review: 0 of 7. Among general-model configurations with valid answers, 89 of 113 did.
Six reviews split four or more of the seven decision models, and three of them carry disputed reference labels. Five of Jev's six misses are in that set, so the misses were not random and you can route reviews like these to a person.
Every Jev answer comes with a confidence score. The calibration gap is the average distance between how sure a model says it is and how often it is right, so lower is better. Over its 720 answers, Jev's gap was 0.011, against 0.358 for Clef Flash. Jev was still 0.96 confident on a wrong testimonial answer. Its ten least-confident reviews include 7 of the 10 hardest, so the score points at hard reviews, and it still lets a wrong answer through at the top of the scale.
Going from classifier instructions (P1) to step-by-step decision rules (P2) raised the score for 4 of 39 setups, left 14 unchanged and lowered 21.
Calibration gap, lower is better
P1 to P2, 39 setups
Send everything else to a person. The rule works when the two models make different mistakes.
$0.0375 for both runs over all 60 reviews.
$0.0685 for both runs. Other passes of this pair accept different counts: with Gemma's second fresh pass, 1 error got through.
35of 60 reviews reach a person under the full policy
With Solar + Perplexity, 7 reviews go to a person because the two answers differ, 24 because either model flags a serious concern, and 4 because either model says can't tell. The other 25 are accepted with no routing. We put a lot of serious concerns in this set on purpose, so a normal pile would make a shorter queue.
Four steps, and none of them needs a big budget.
Pull 60 of your own cases and label them yourself before any model sees them.
Give every question a can't-tell option, so a review that doesn't fit has somewhere to go.
Run two cheap models and keep only what they agree on.
Count how many land in the human queue, and check that the rare cases you care about got through.